
Why This Announcement Caught My Attention
TypeSafe’s announcement of Jev caught my attention because the idea behind it connects to something I’ve been thinking about for a while. Daniel Kahneman’s Thinking, Fast and Slow inspired them, and it inspired me too.
The book describes two modes of thinking: fast, intuitive judgments and slower, deliberate reasoning. It also explores how intuition can lead us into mistakes. That distinction provides a useful way to think about where software should act quickly and where it should pause for more analysis. About the book
For me, the connection to AI is straightforward: why should every decision in an automated workflow require the same kind of processing? Recognizing that a message is an appointment request is a different task from resolving a complaint involving several conversations and an exception to company policy. Both matter, but the work involved is different.
That question is especially relevant to what we build at Digital Outbreak. Our websites and AI features help businesses capture inquiries, and our funnels and follow-up systems connect those inquiries to the next action. There are plenty of small decisions between a customer reaching out and someone actually helping them. Making those decisions faster, at a lower cost, could change how much of that process we can usefully automate.
What Did TypeSafe Announce?
TypeSafe announced Jev on September 15, 2026, as its first System One model, available through early access. It is designed to return structured decisions rather than generate open-ended text. The company reports response times of 70–500 milliseconds and large efficiency gains on its evaluations, while acknowledging that its largest gains are likely toward the upper end of real-world results. Read TypeSafe’s announcement
The documentation describes sending context alongside specific questions, such as selecting an option or scoring something against a rubric. Multiple independent questions can be evaluated in parallel. That gives software values it can use to decide what happens next.
In an automation, answering a narrow question and composing a customer response can be separate jobs. We might need to determine which department owns a request before deciding whether any message should be written. That separation is useful because it lets us choose the right tool for each job.
| Part of the work | Approach we would evaluate | Example |
|---|---|---|
| Checking a known fact | Business rule or database lookup | Is this address inside the service area? |
| Interpreting a short request | Fast decision model | Is the customer asking to book, reschedule, or discuss a bill? |
| Writing a response | Language model or approved template | Ask for the missing job details in plain language. |
| Resolving conflicting context | Deeper analysis with records | Does the new message change what was agreed earlier? |
| Making an exception | Authorized staff member | Decide whether to offer a refund or override a policy. |
This is a design comparison, not a claim that each approach performs equally well. The right choice depends on the specific decision and what happens if it is wrong.
The distinction between a valid output and a correct judgment matters here. TypeSafe guarantees schema matching and uses that in its discussion of hallucination. An output can still fit the allowed structure while choosing the wrong category. I would evaluate those as separate questions: did the response follow the required format, and did it make the right decision?
These are vendor claims, not results we’ve reproduced at Digital Outbreak. What interests me enough to test is the possibility of putting this kind of decision-making into everyday workflows.
Where Could This Fit at Digital Outbreak?
The clearest opportunities are the repeated judgments inside lead handling, customer intake, and follow-up. Those are places where a small delay or a wrong handoff can affect the customer’s experience. The examples below are ways I would explore applying this approach, not claims that we have deployed Jev in client systems.
Getting an inquiry to the right person
Imagine a service business receiving messages about new work, existing appointments, billing, and urgent problems through the same form. A useful first step is identifying what each person needs and putting the request in the right queue.
A fast decision model could help interpret the message, flag possible urgency, and identify whether the request needs review. The business would still define who receives it and what happens next. That could reduce the time someone spends opening and sorting routine inquiries.
Making follow-up reflect the conversation
Follow-up should respond to what the customer has actually said. A person asking for a callback tomorrow needs a different next step from someone who has already booked or says they are no longer interested.
An interpretation step could help recognize those differences before the next action is selected. Confirmed bookings, communication permissions, and explicit opt-outs should remain authoritative records and rules in the system. The opportunity is to handle the meaning of less structured replies more efficiently, while keeping those rules in control.
Helping staff see what needs attention
An intake process can collect a message without collecting enough information to act on it. The customer might describe the problem but leave out the location, or refer to a previous visit without enough detail to identify the job.
A decision layer could flag incomplete context for staff or a separate response step. It could also distinguish an ordinary new inquiry from a conversation that needs someone to read the history carefully. That would be useful even if the final response still comes from a person.
What Could a Customer Request Look Like from Start to Finish?
A useful automation would carry the request toward a clear owner and next action while preserving the context that matters. Here’s an illustrative service-business example of how fast decisions could work alongside records and human judgment.
A customer writes: “Can someone come today? You repaired this last month, and it’s happening again.” There are several things to understand in that short message: a request for service, a possible repeat problem, and a preference for help today. There are also things we do not know, including the exact problem, the previous work, and whether a same-day visit is available.
The first useful step is connecting the request to the right customer and job, if a reliable match exists. A model should not invent a previous visit or assume that the work is covered by a warranty. The record supplies those facts; the message supplies the customer’s current concern.
Fast interpretation could then flag the request as a possible repeat issue and identify the information needed for a handoff. If the business requires staff to review repeat repairs, that rule would determine the destination regardless of how confident the model was. The customer could receive an appropriate acknowledgment without the system promising a technician, a price, or coverage it has not confirmed.
The other branches matter too. A routine new inquiry with complete details might move directly into an approved intake process. A request with an uncertain location might need one clarifying question. An urgent concern should reach the responsible person through the business’s escalation process, without getting stuck in repeated attempts to classify it.
The result we would want is a staff member opening a request with the relevant history already connected and the next action clear. They should spend less time reconstructing the conversation and more time helping the customer. This is where custom AI development and integrations connect to everyday operations: the model’s judgment only becomes useful when the surrounding system follows through.
How Could This Make Automations More Efficient?
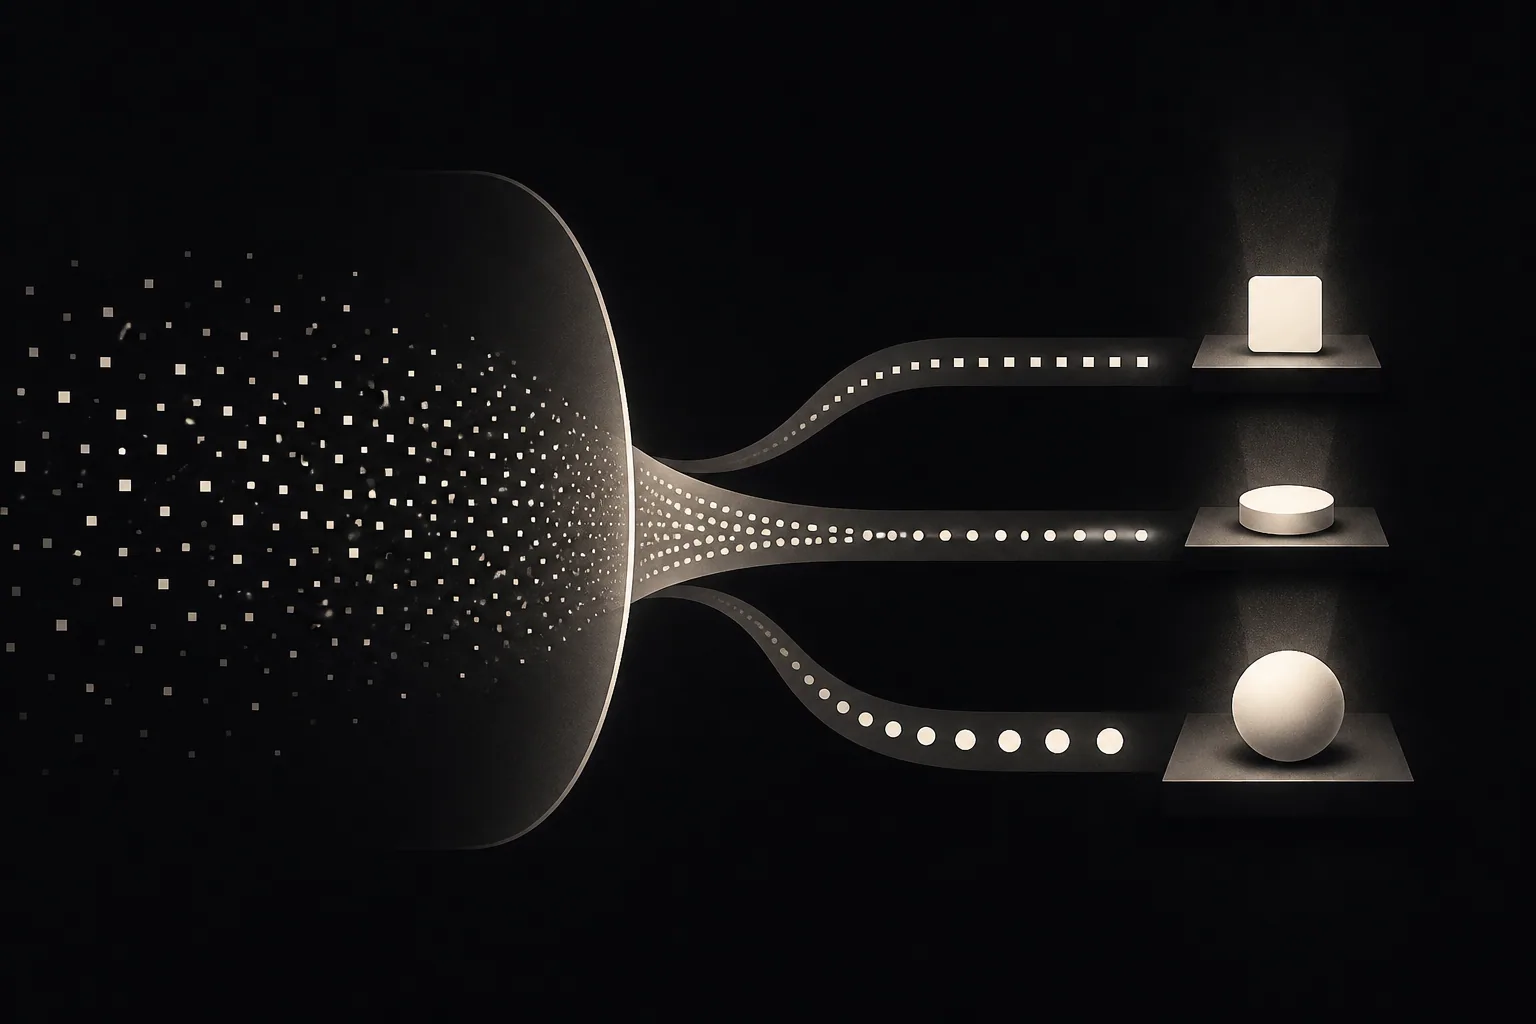
The potential efficiency gain comes from matching each task to the amount of processing it needs. Some steps only need a rule or a lookup. Others need a quick interpretation. A smaller number require a longer investigation or a human decision.
Consider a purely illustrative workload of 10,000 incoming requests a month. If testing showed that 8,000 could be handled correctly through a fast decision path, deeper analysis could focus on the remaining 2,000. Those numbers are an example, not a forecast of Jev’s accuracy or our expected savings.
Even in that example, 80% of requests taking the fast path would not automatically mean an 80% reduction in cost. All 10,000 requests would still incur the cost of the initial decision, and the other 2,000 would need additional processing. Integration costs and any staff time would also remain part of the total.
Speed needs the same care. Independent checks may be evaluated together, while a decision that depends on a customer lookup must wait for that lookup. TypeSafe’s documented patterns include grouping questions, routing by intent, and using confidence to influence the next step. Those are useful building blocks, but the order and dependencies of the complete workflow still matter.
The useful question would be whether the complete system becomes cheaper and faster while maintaining the quality of its decisions. That includes the cost of correcting mistakes, repeated attempts, and staff review. A lower price per model call can disappear quickly if it sends customers to the wrong team.
There is also a development benefit worth exploring. Well-defined decisions give us smaller pieces to evaluate and improve. We could investigate a weak urgency classifier without having to judge an entire customer conversation as one large success or failure.
Faster, cheaper judgments could let us automate more routine work and spend more attention on the exceptions that actually need it.
For a business owner, the outcome should be visible in the operation: less sorting, fewer unnecessary handoffs, and a shorter wait for the right response. Those are the improvements I would want to demonstrate.
Lower operating costs could also make smaller automations worth building. A business may have an awkward task that only saves a little time per request, such as identifying which replies need another team member’s attention. If that task becomes inexpensive enough to run consistently, the accumulated reduction in manual work could justify including it. We would still weigh that benefit against the effort required to maintain the integration.
Why Keep Fast and Slow Thinking Together?
A fast path is more useful when the system can recognize when to ask for additional analysis. Some requests are ambiguous, and some decisions deserve review even when the model appears certain.
The RustBrain paper, submitted in March 2025, explores a related idea in a different setting: repairing undefined behavior in Rust programs. Its fast process proposes solutions, while its slow process decomposes, verifies, and generalizes, feeding information back into further attempts. The authors report a 94.3% pass rate and an 80.4% execution rate on their Miri-based evaluation. Read the full paper
RustBrain is a separate research framework, not the technology behind Jev, and those results don’t establish performance for business automation. What I take from it is the value of connecting proposal and verification rather than treating a quick answer as the end of the process.
For our work, that could mean a routine request moves forward quickly while an unclear request gets more context, deeper reasoning, or a staff review. The slower path should have access to something useful, such as the conversation history or a verified business record. Simply asking another model to repeat a guess would not be much of an improvement.
What Would We Test Before Using It?
We would test whether the model makes the right decisions on representative business requests and whether the entire workflow improves. An impressive demonstration is a reason to investigate, not enough evidence to make promises to a client.
TypeSafe’s confidence documentation says its Choice and Score answers include probability distributions and a confidence measure derived from those distributions. That confidence value should not be casually read as a guaranteed percentage chance that an answer is correct. We would need to examine how it relates to errors in the specific task we are testing.
The practical evaluation would cover:
- Decision quality: Does the request reach the right destination, especially when the wording is vague or contradictory?
- Exception handling: Does the system flag uncertain cases, and how often does it confidently get something wrong?
- End-to-end speed: How long does the customer or staff member wait once lookups, integrations, and retries are included?
- Total cost: What does each correctly completed workflow cost after review and correction?
- Business outcomes: Are there fewer missed handoffs and less manual work without creating new customer problems?
We would also compare the proposed model with simpler alternatives. A known service area should usually be checked against a list. A confirmed appointment should be read from the scheduling system. Using AI where it adds useful interpretation leaves fewer unnecessary decisions to get wrong.
What Would a Breakthrough Look Like for Our Clients?
A breakthrough would be making useful automation practical in parts of a business that are currently too expensive, too slow, or too awkward to automate well. That could mean handling a higher volume of inquiries without adding the same amount of sorting work, or checking each incoming conversation for a needed handoff without making the customer wait longer.
That’s why this announcement matters to me. The idea from Thinking, Fast and Slow has been on my mind for a while, and seeing it applied to this kind of model gives us something concrete to evaluate.
At Digital Outbreak, I want that evaluation to lead back to the work our clients care about: capturing the inquiry, understanding what is needed, getting it to the right person, and following through. If models like Jev can make those decisions reliably at a lower cost, we can build more efficient automations and extend them to more of the everyday work around a business.
If your team still spends time sorting inquiries or manually deciding what happens after each reply, that’s a useful place to start a conversation about automation. We can identify the decisions involved and assess where a faster, more focused AI step would actually help.